Available · reviewer-lead, QA, research roles

Adnan Shamim Dar

AI Researcher · Medical AI Evaluator

I find what's wrong with AI before your users do. Then I build systems that don't make those mistakes.

About

Most people who grade AI can tell you an answer is wrong. Few can tell you why it's dangerous, fix it, and write the rule that makes the next thousand reviewers catch it too.

That's the job I do. I'm an AI researcher, a medical student at UNIVPM, and a Trusted-tier reviewer on Mercor, where I was picked for the top-performer incentive. In the last year I've worked on 20+ AI training projects for frontier labs. I've written the prompts that break models, ranked their answers, red-teamed their agents, and audited other experts' work before it reached the client.

When I'm not judging AI, I'm building it: an artificial-life lab, a cancer-research engine and a private AI runtime. See them below ↓

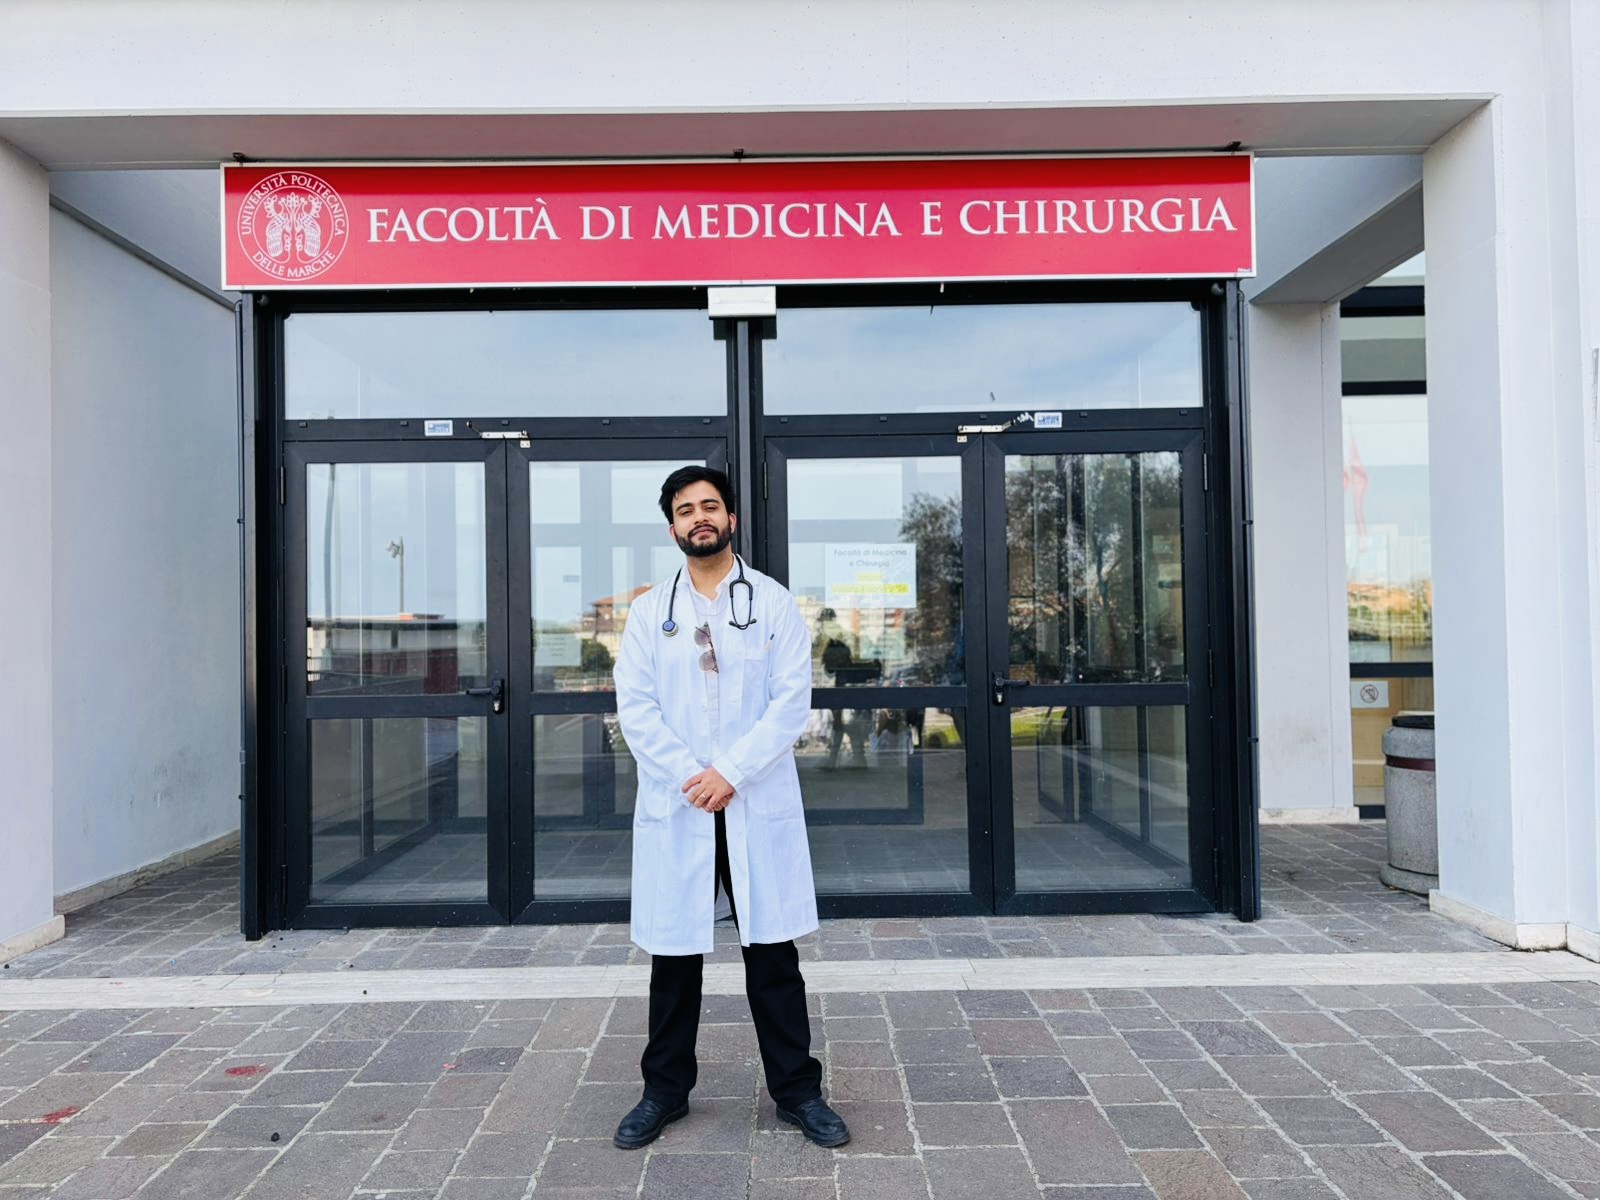
Adnan Shamim Dar in a white coat outside the Faculty of Medicine and Surgery, UNIVPM
20+AI training projects
80+expert reviews in my first 3 weeks
6 in 10submissions I send back
27k+research evaluations run

Trusted by the platforms that train frontier models

  • Mercor
  • micro1
  • Outlier Scale AI
  • Labelbox
  • Alignerr
  • Ermis
  • ID-verified & background-checked
  • IMAT 104th worldwide
  • ERDIS merit scholar
  • 5 languages · IELTS 8.5
  • Open-source on GitHub

Experience

AI labs pay me to judge their models. Here's where.

  1. Jul 2026 – now

    Mercor · Expert contractor

    Trusted QA Reviewer · Project Odin Oct 2026 – now

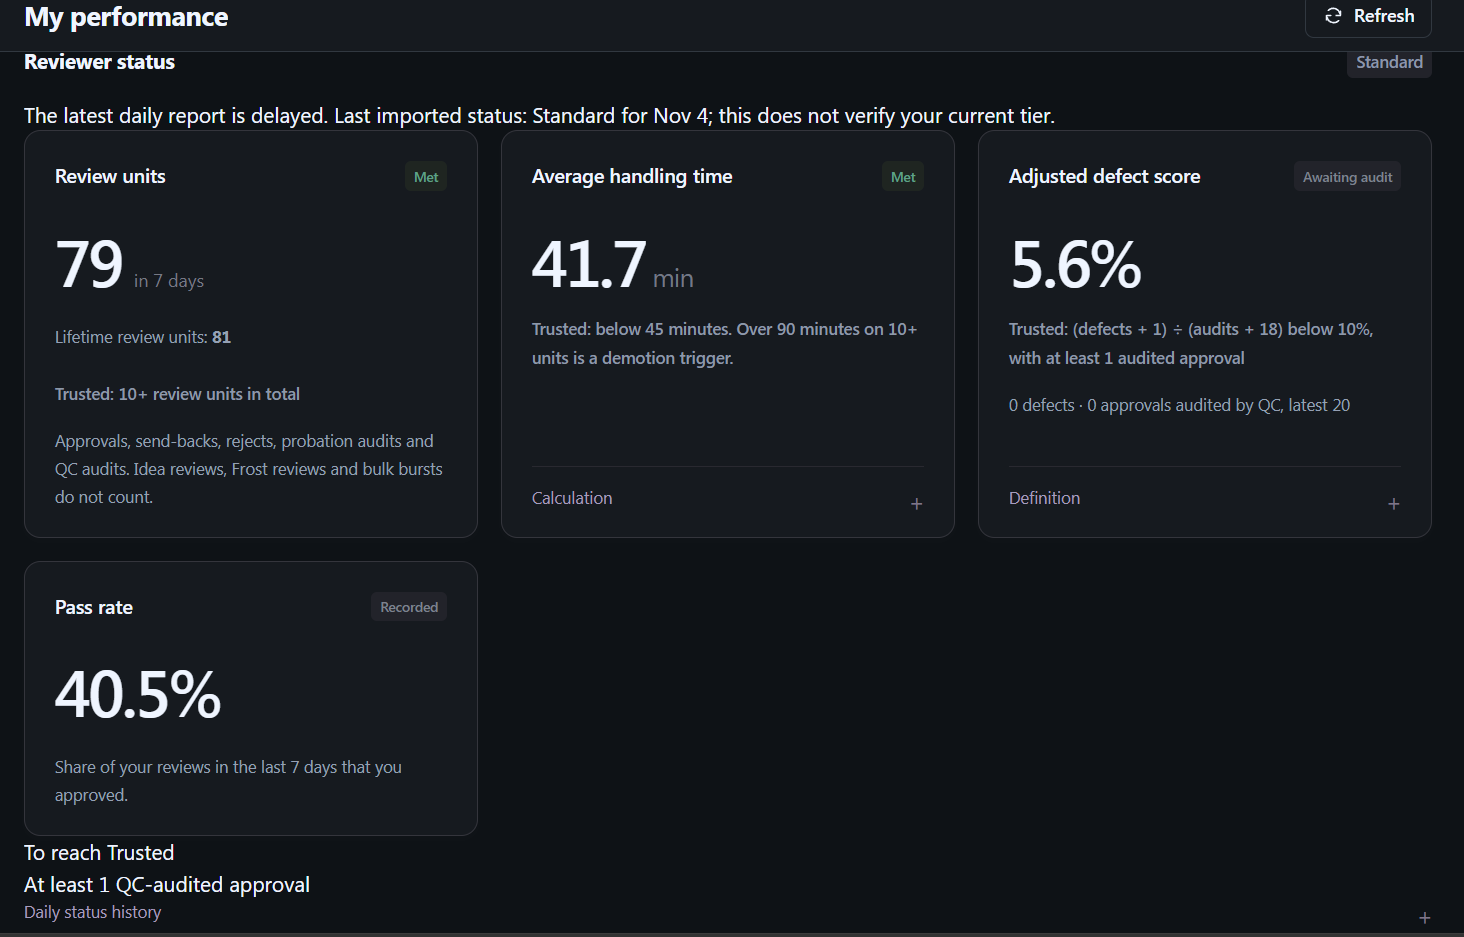
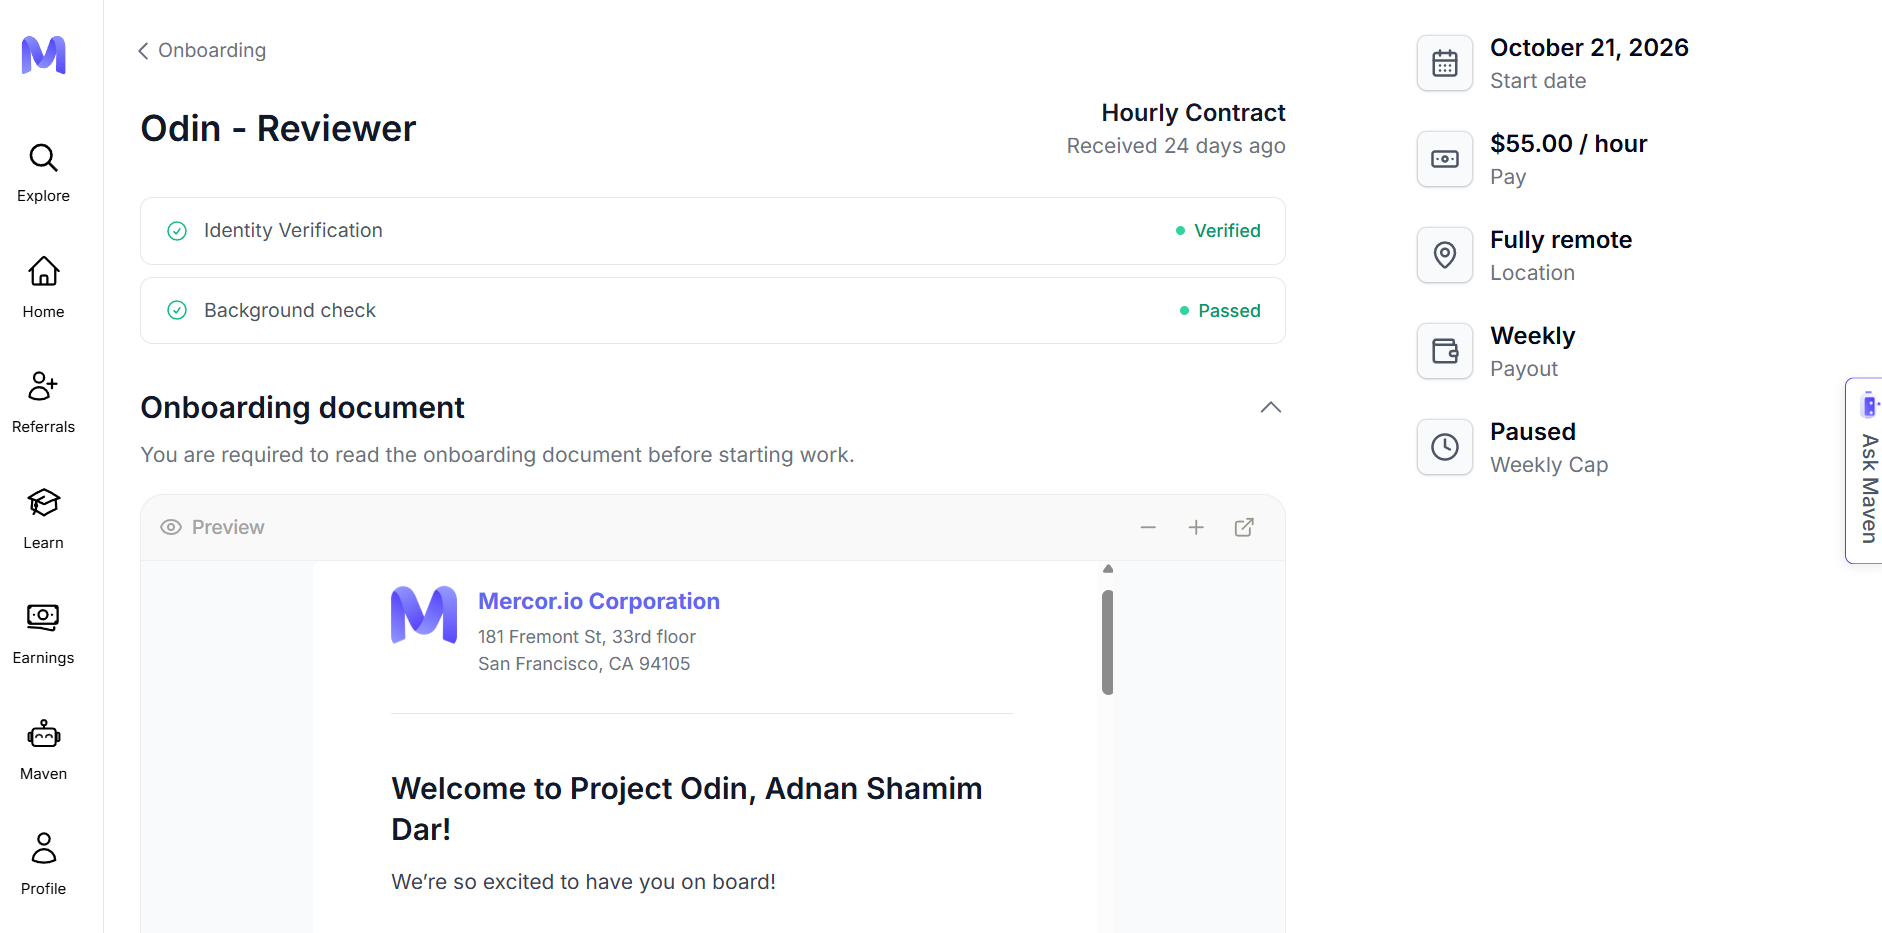
    Other experts record computer-use agent tasks. I decide whether they ship. I was brought in straight at reviewer level, passed identity and background checks, made the Trusted tier, and was selected for the top-performer incentive.

    • 80+reviews in my first three weeks
    • <45 minper review, on target every time
    • 6 in 10sent back, each with written fixes
    Odin reviewer performance dashboard Odin reviewer contract: identity verified, background check passed

    Expert Design Grader · Feather Jul 2026

    I graded AI-generated slide decks for an enterprise client: six task types, a 1–7 scale and a 45-minute clock per task. Every score needed written evidence, slide by slide. I also wrote my own 22,000-character grading manual so my verdicts held up under review.

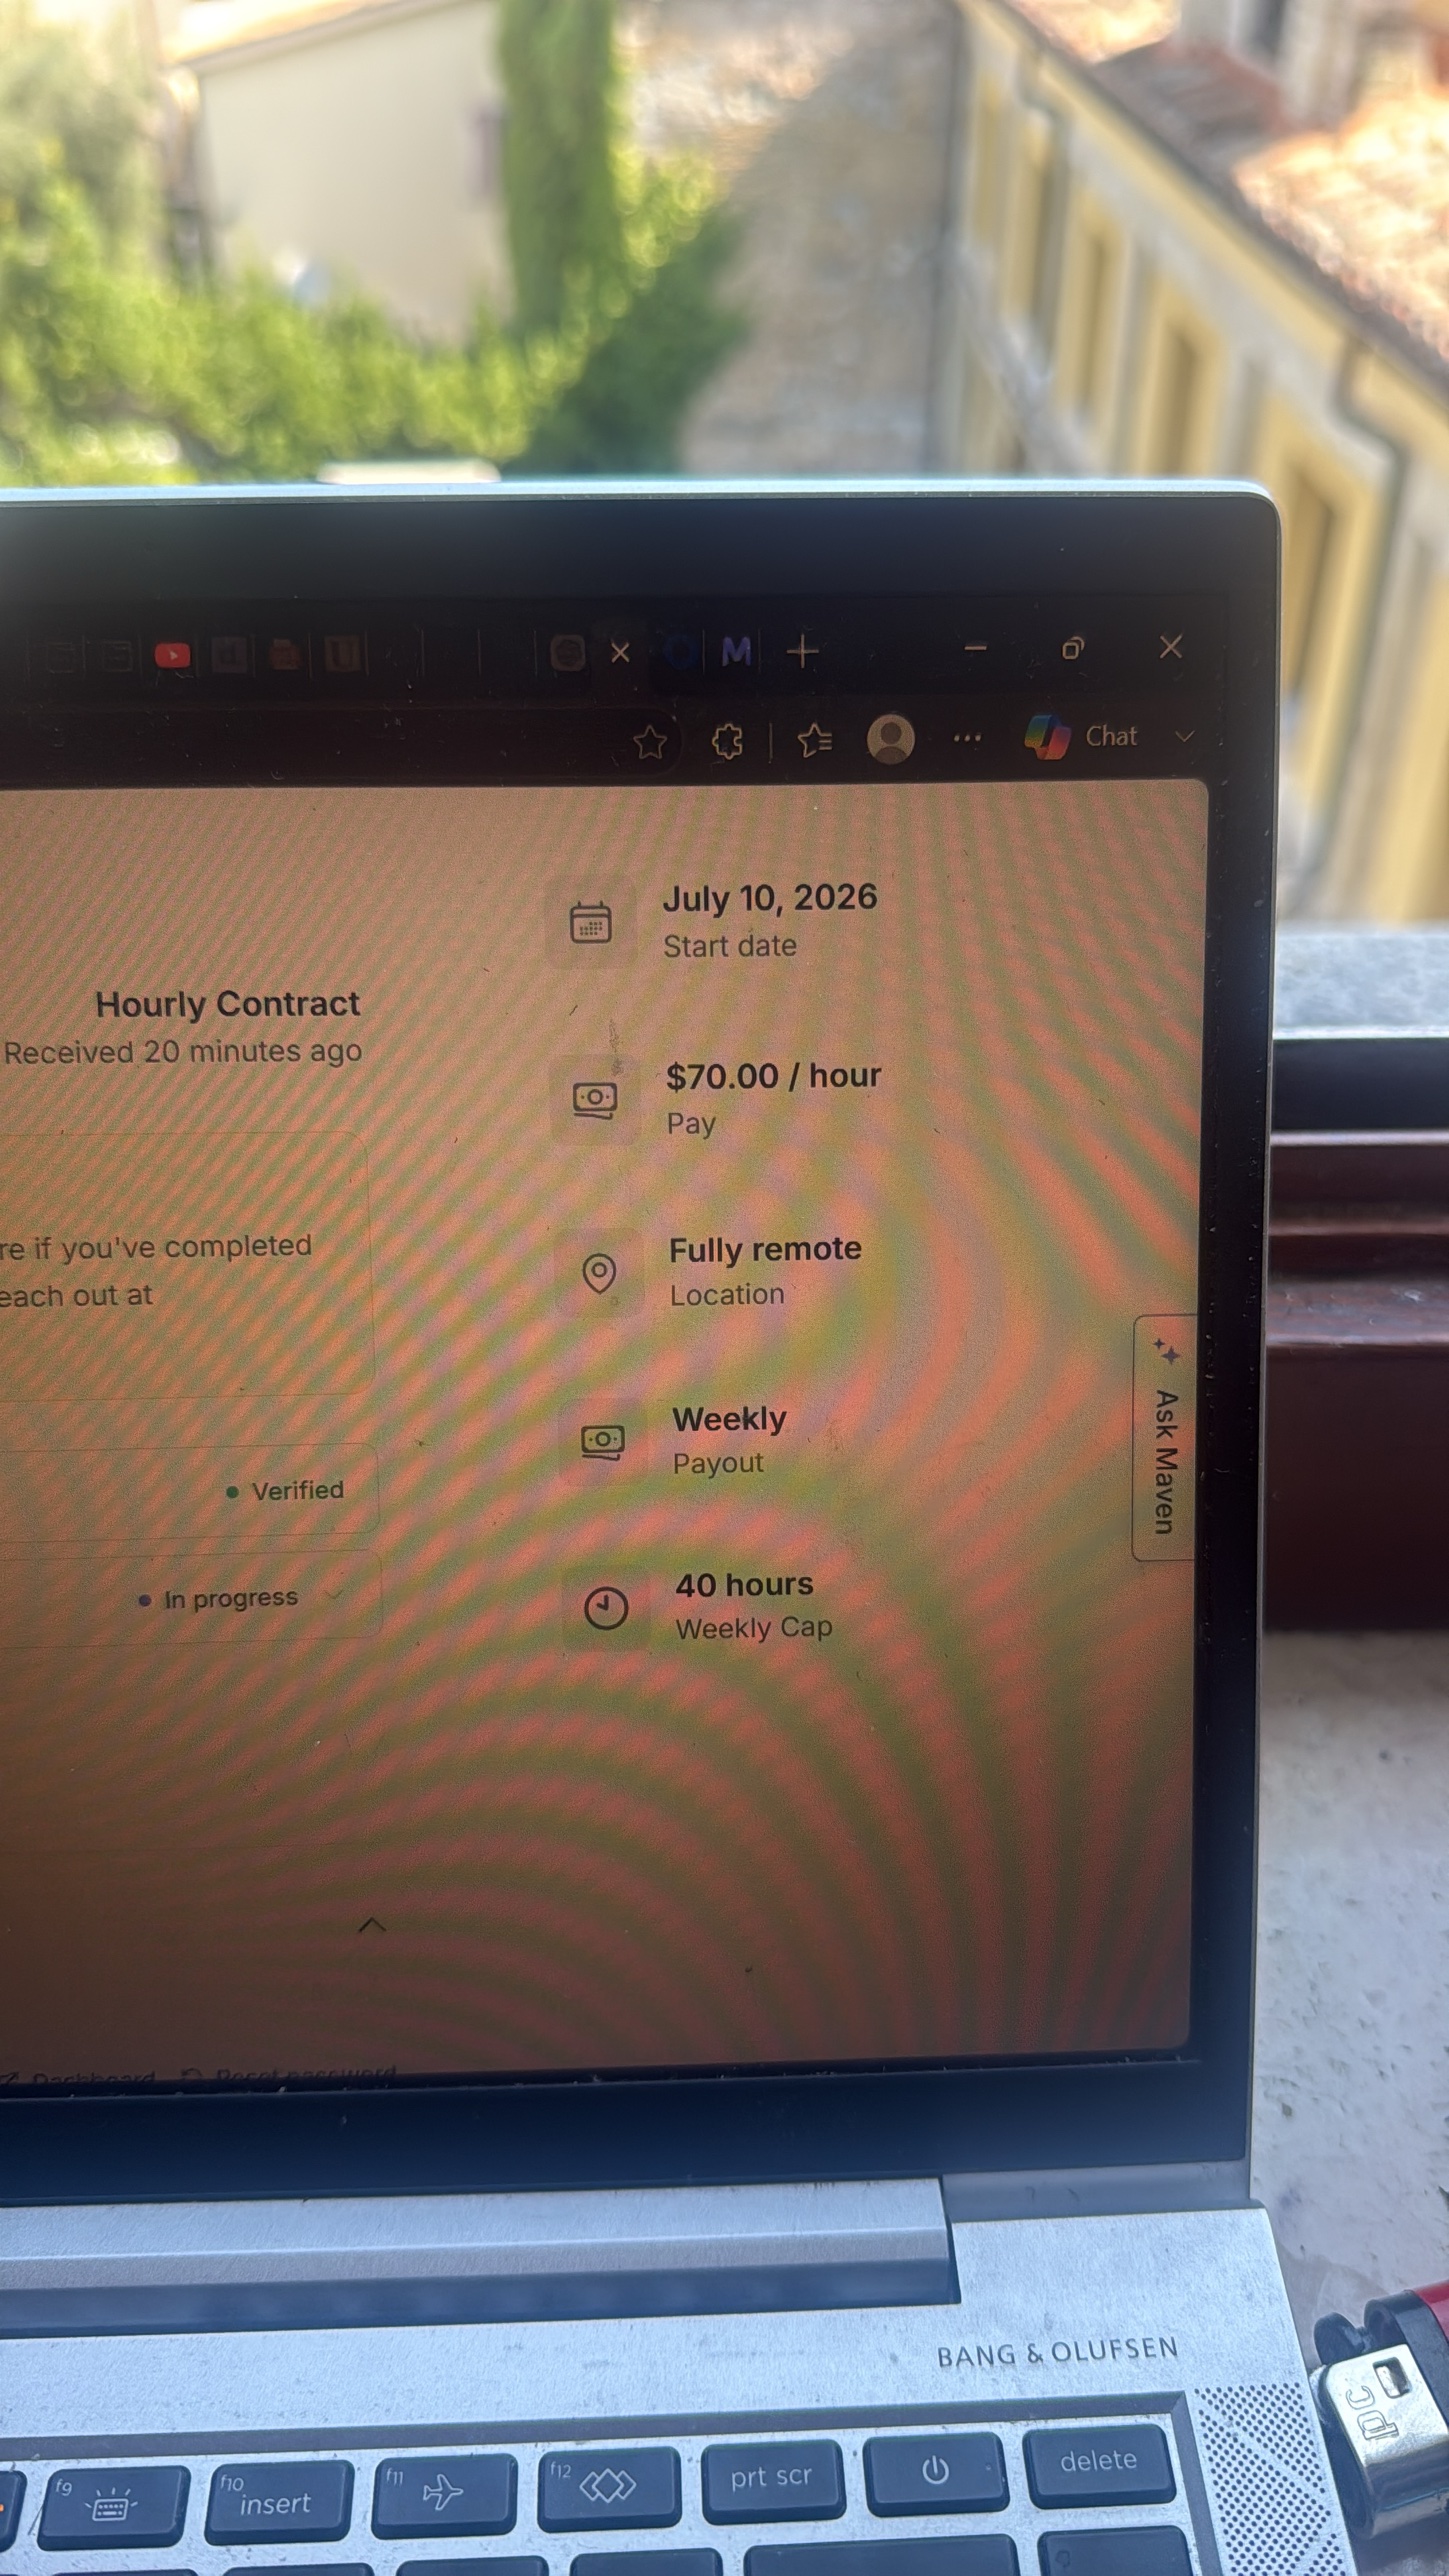
    Mercor expert hourly contract, July 2026
    • Agent trajectory review
    • QA checklists
    • Rubric grading
    • Contributor feedback
    Case study & proof
  2. Sep – Oct 2026

    micro1 · Robotics data annotator

    Project Titan Proton. Robots learn from video, and someone has to say exactly when the motion stops being useful. I tagged robotics task footage frame by frame, marking idle time, wasted motion and task progress. 100% on both certification quizzes.

    • Video annotation
    • Temporal tagging
    • Embodied AI
    Case study & proof
  3. Oct 2026

    Labelbox / Alignerr · Voice-agent red-teamer

    I called a clinic's AI receptionist and tried to break it. I checked that it called the right tool at the right moment (identity checks, bookings, patient lookup), then tried to trick it into unsafe help and into leaking its own system prompt. I'm also qualified on Alignerr as a Biology Subject Matter Expert.

    • Function calling
    • Voice agents
    • Prompt injection
    Case study & proof
  4. Dec 2025 – Nov 2026

    Outlier · Scale AI · Medical expert & multilingual evaluator

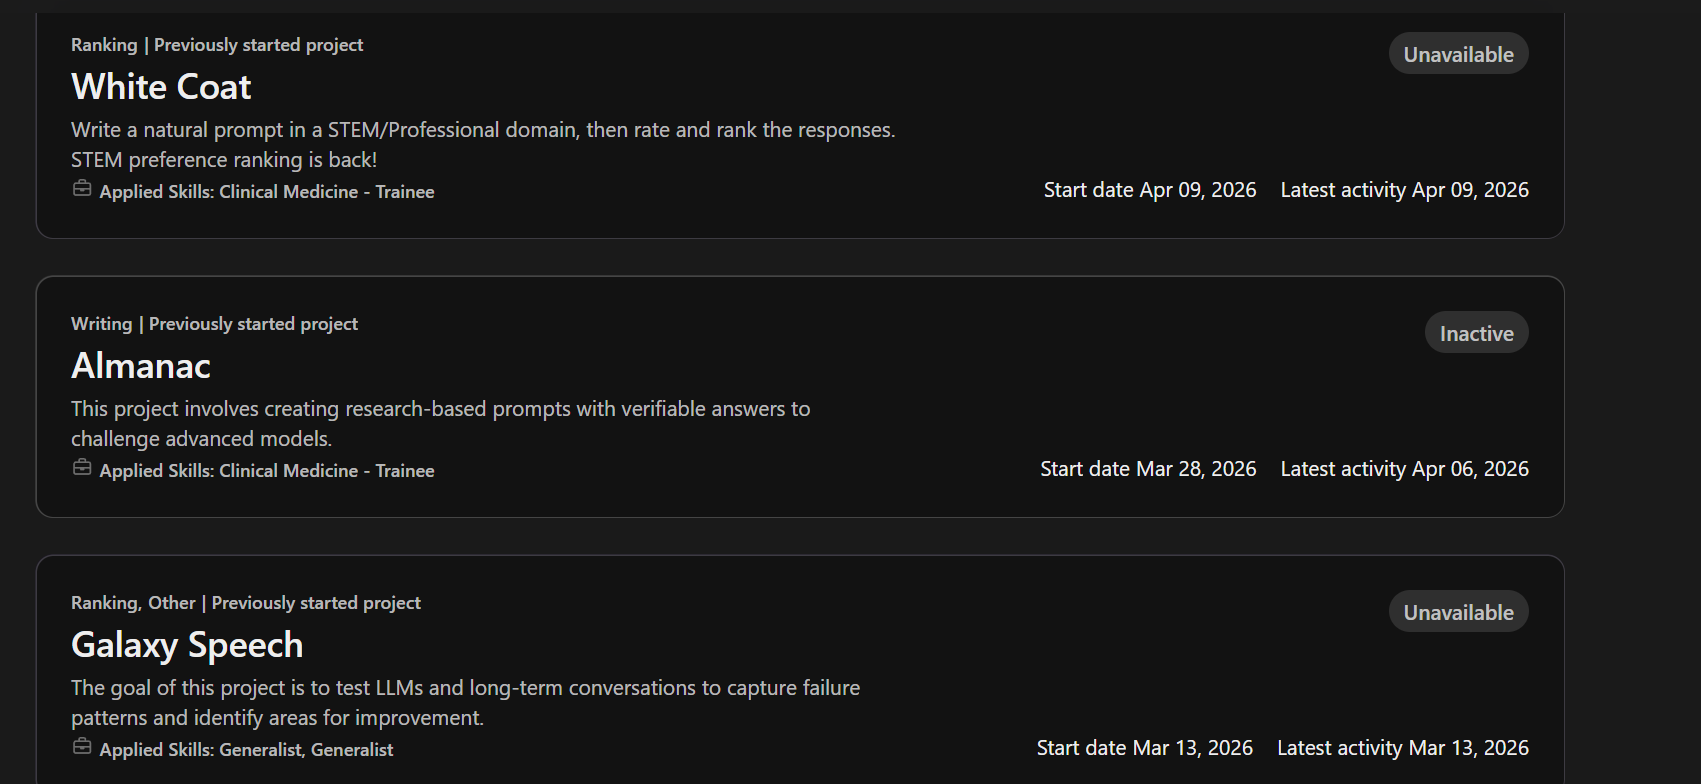
    • White Coat, Almanac: I wrote clinical and research prompts with verifiable answers, designed to make frontier models fail, then ranked what they said.
    • Galaxy Speech: I kept models talking for long multi-turn conversations to find where they fall apart.
    • Aether, Multimango: Italian-language evaluation and speech-recognition test sets.
    • Sixth Sense, Mime Orchard, Cribbage Tail and more: attempter and reviewer work. Access to these projects depends on keeping a high quality score.
    • RLHF
    • Medical review
    • Adversarial prompts
    • Italian
    Outlier project history: White Coat, Almanac, Galaxy Speech
    Case study & proof
  5. Aug 2026

    Ermis · Audio transcription

    Production speech transcription for model training, done to strict conventions: spoken forms, non-speech tags, overlapping speakers.

Research & builds

I don't just grade AI. I research it and build it.

live simulation

01 AI research · artificial life

Genesis

What happens when you give an AI agent something to lose?

Genesis is my artificial-life lab: single-cell agents that can actually die, and no fitness function telling them what to want. Whatever behaviour shows up has to emerge on its own. I run it like a clinical trial, with powered ablations, null baselines and controls.

  • Fear matters. Remove it and agents reproduce about a third less.
  • Honest numbers. A null baseline showed my own headline metric was inflated, so I cut it by 88%.
  • 455 automated tests. A framework paper is in preparation.
  • Emergent behaviour
  • Agent simulation
  • Experimental design
Case study & proof

02 AI research · computational oncology

NeoResist-MD ↗

Most cancer-AI papers overclaim. I built a research engine that can't.

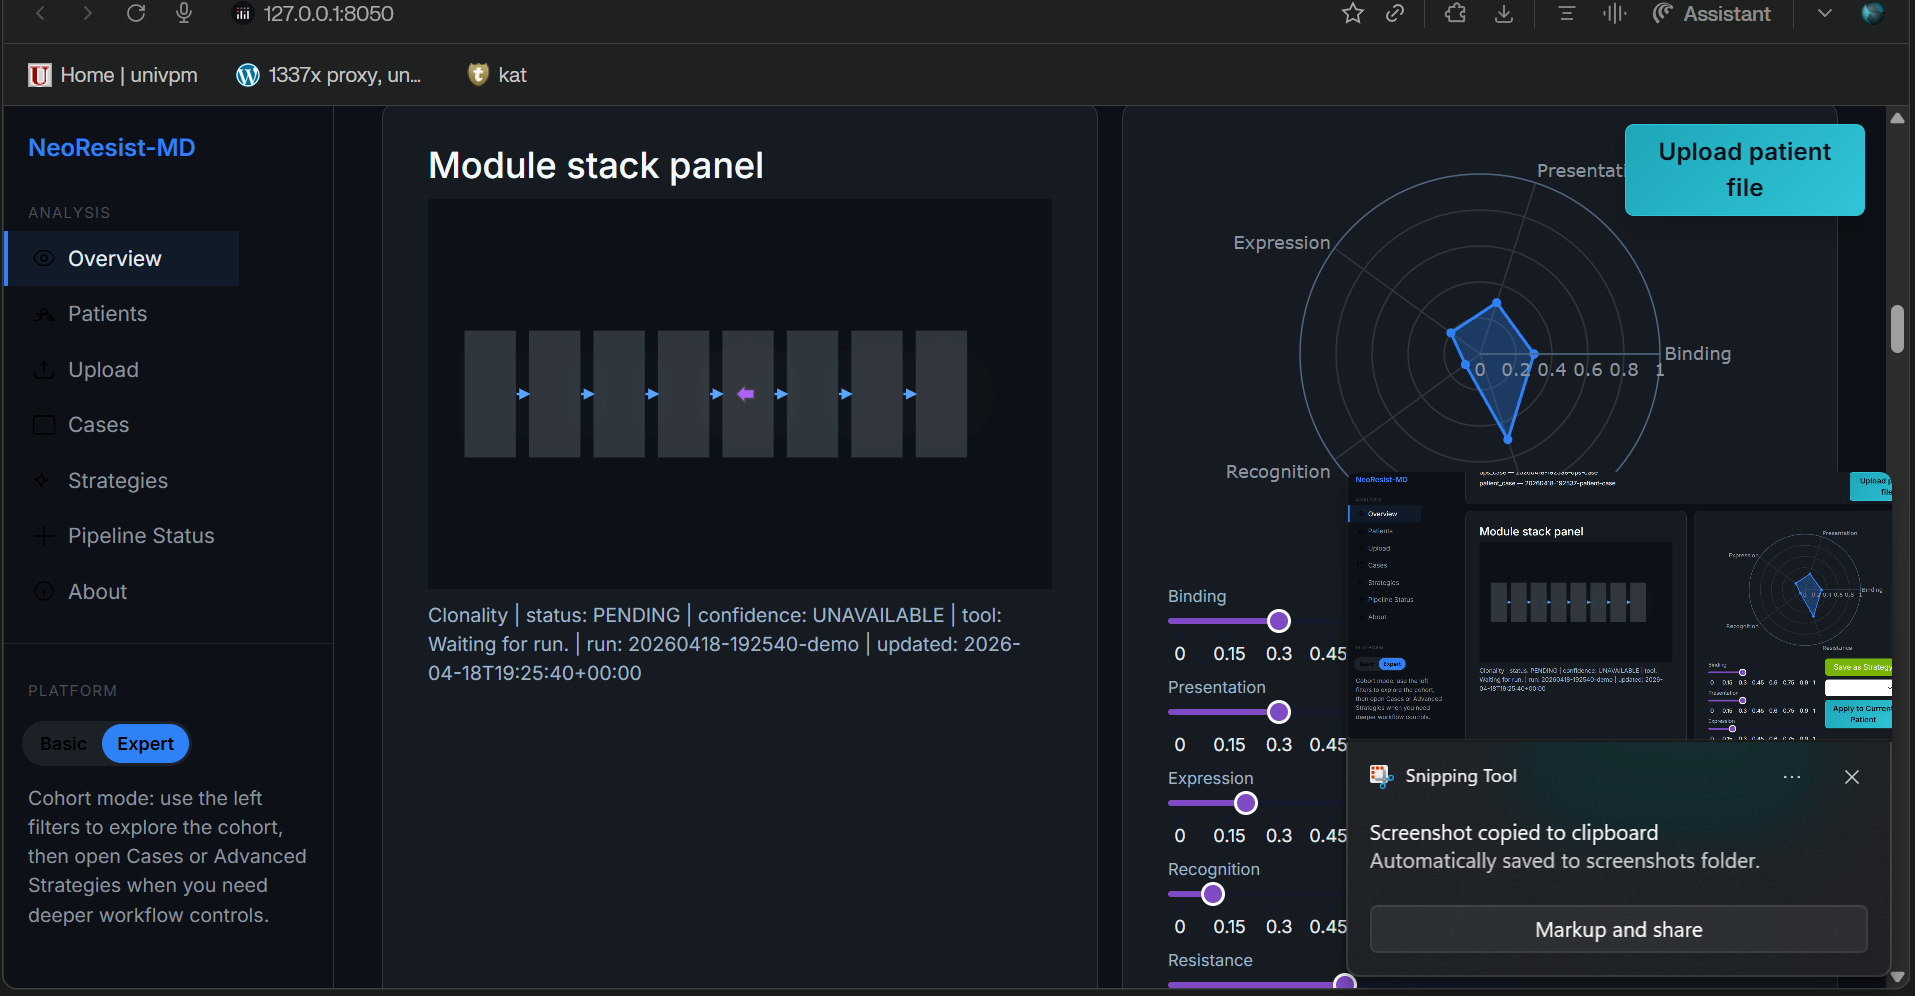
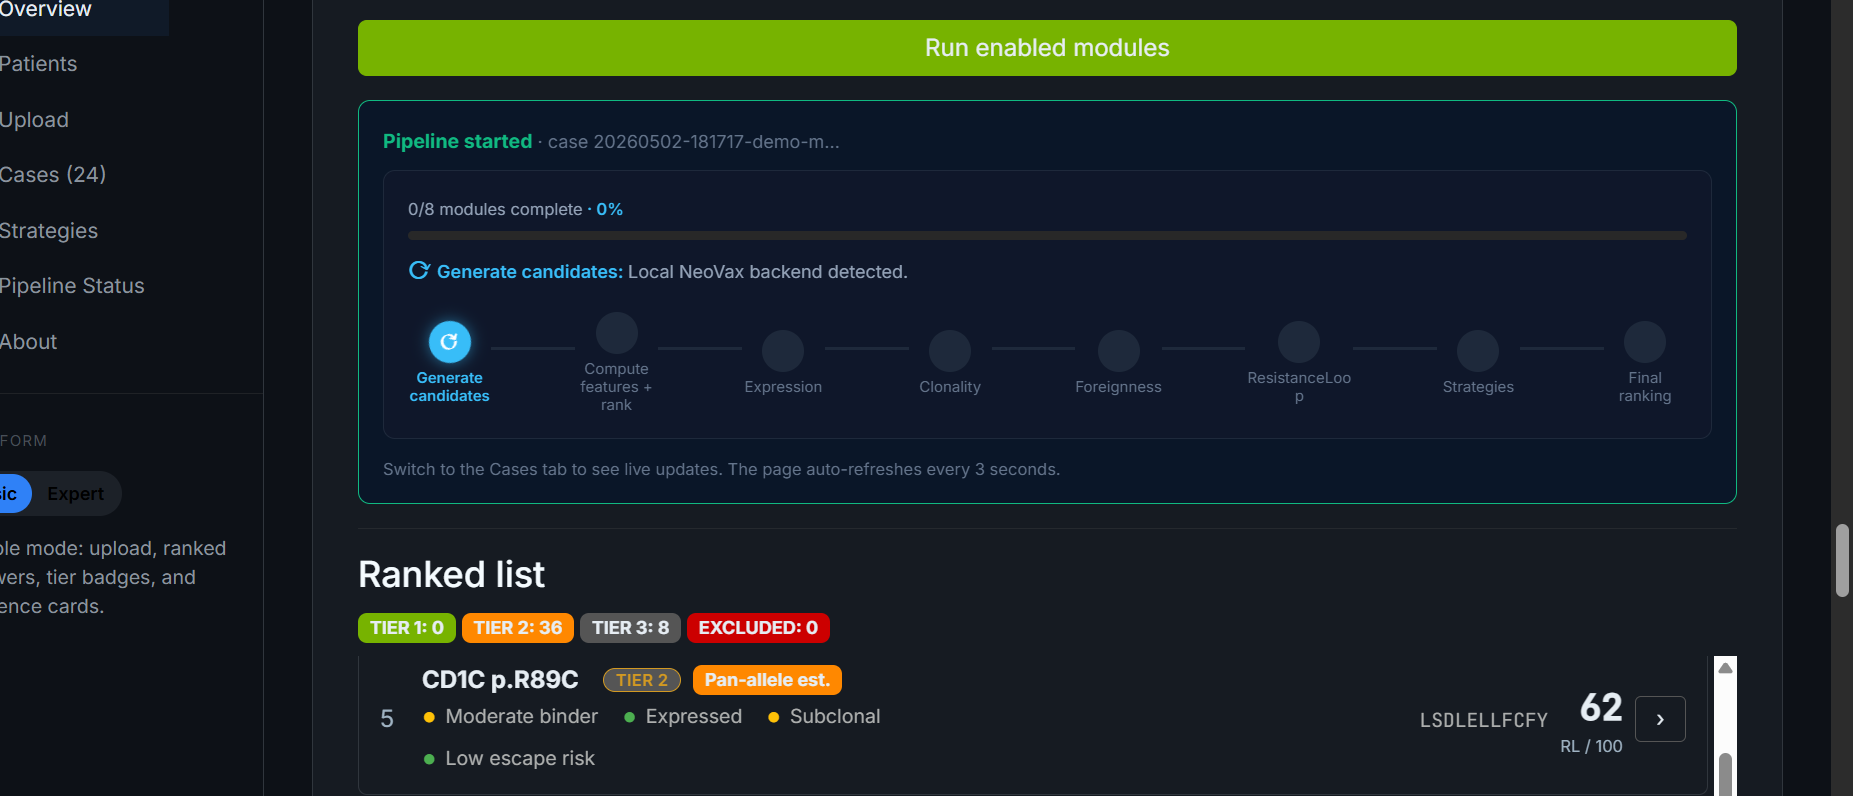
NeoResist-MD hunts for better ways to rank cancer neoantigens, the targets for personalised cancer vaccines. Its discovery engine searched tens of thousands of candidate formulas, and a machine-enforced gate decides which results are allowed to become a claim.

  1. Discoveryideas generated
  2. Held-outtested on unseen data
  3. Claimonly if it survives
  • 27k+evaluations
  • 9cancer contexts
  • 0unearned claims
Case study & proof
NeoResist-MD pipeline with ranked candidate output NeoResist-MD module dashboard

03 Systems engineering · private AI

Tandem

Your own private AI, on hardware you already own. No cloud. No telemetry.

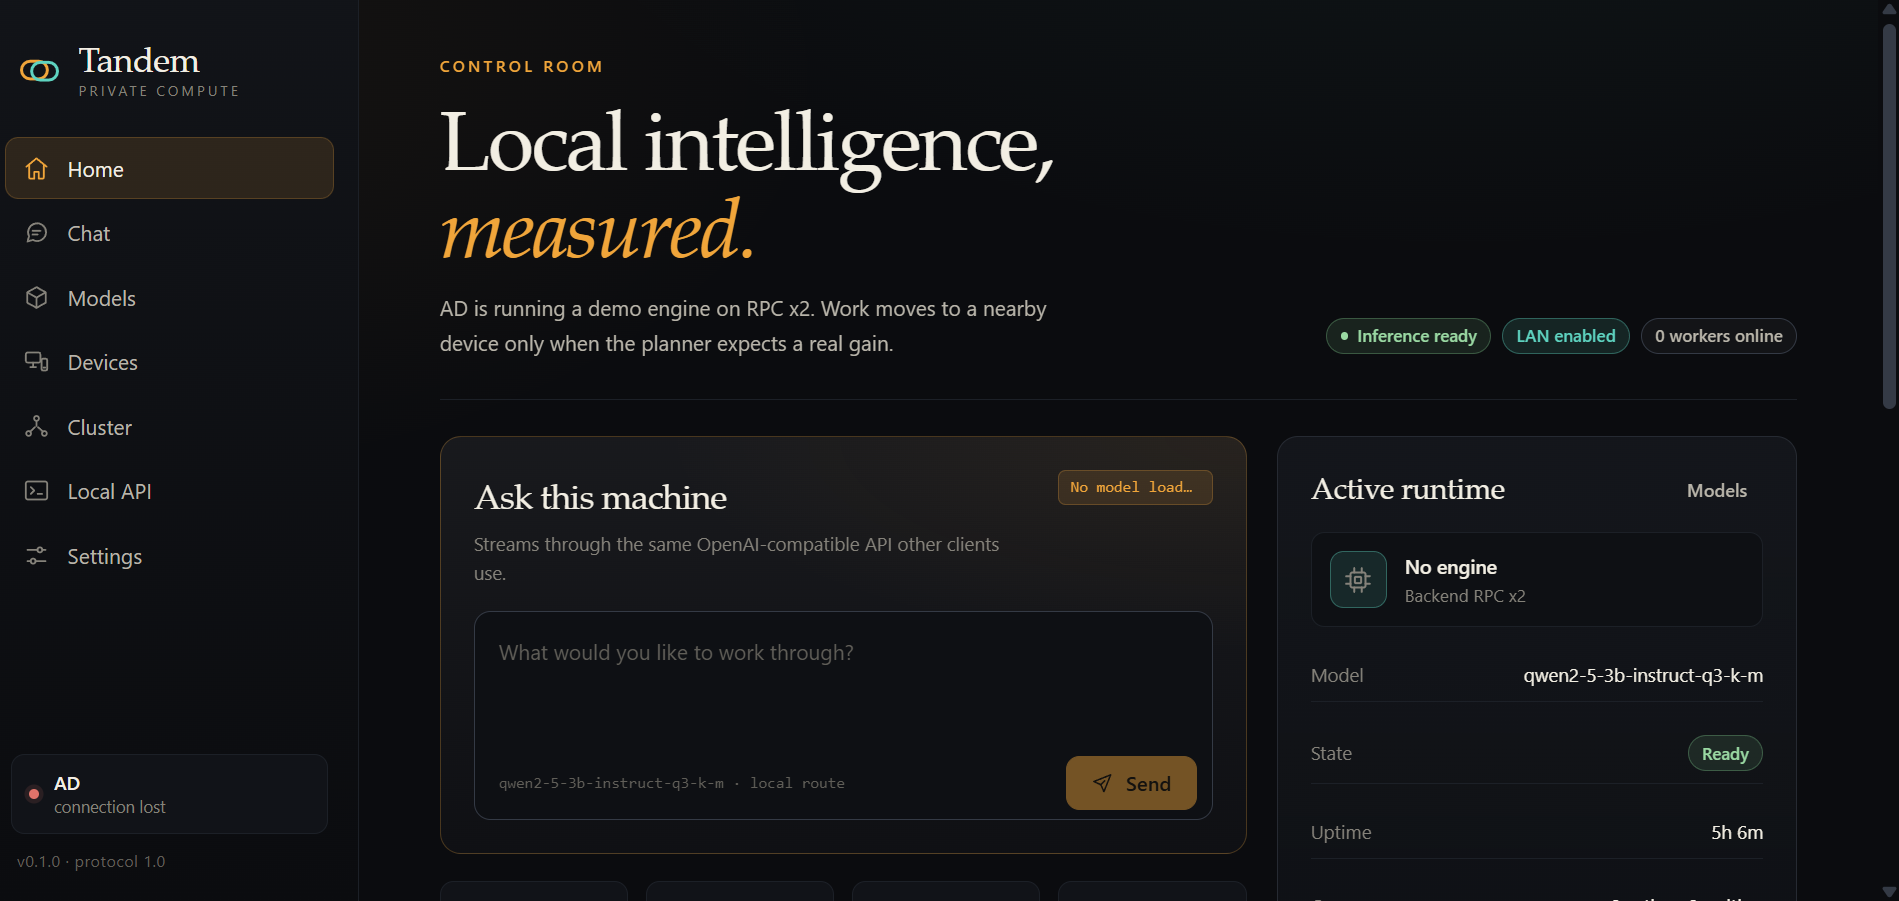
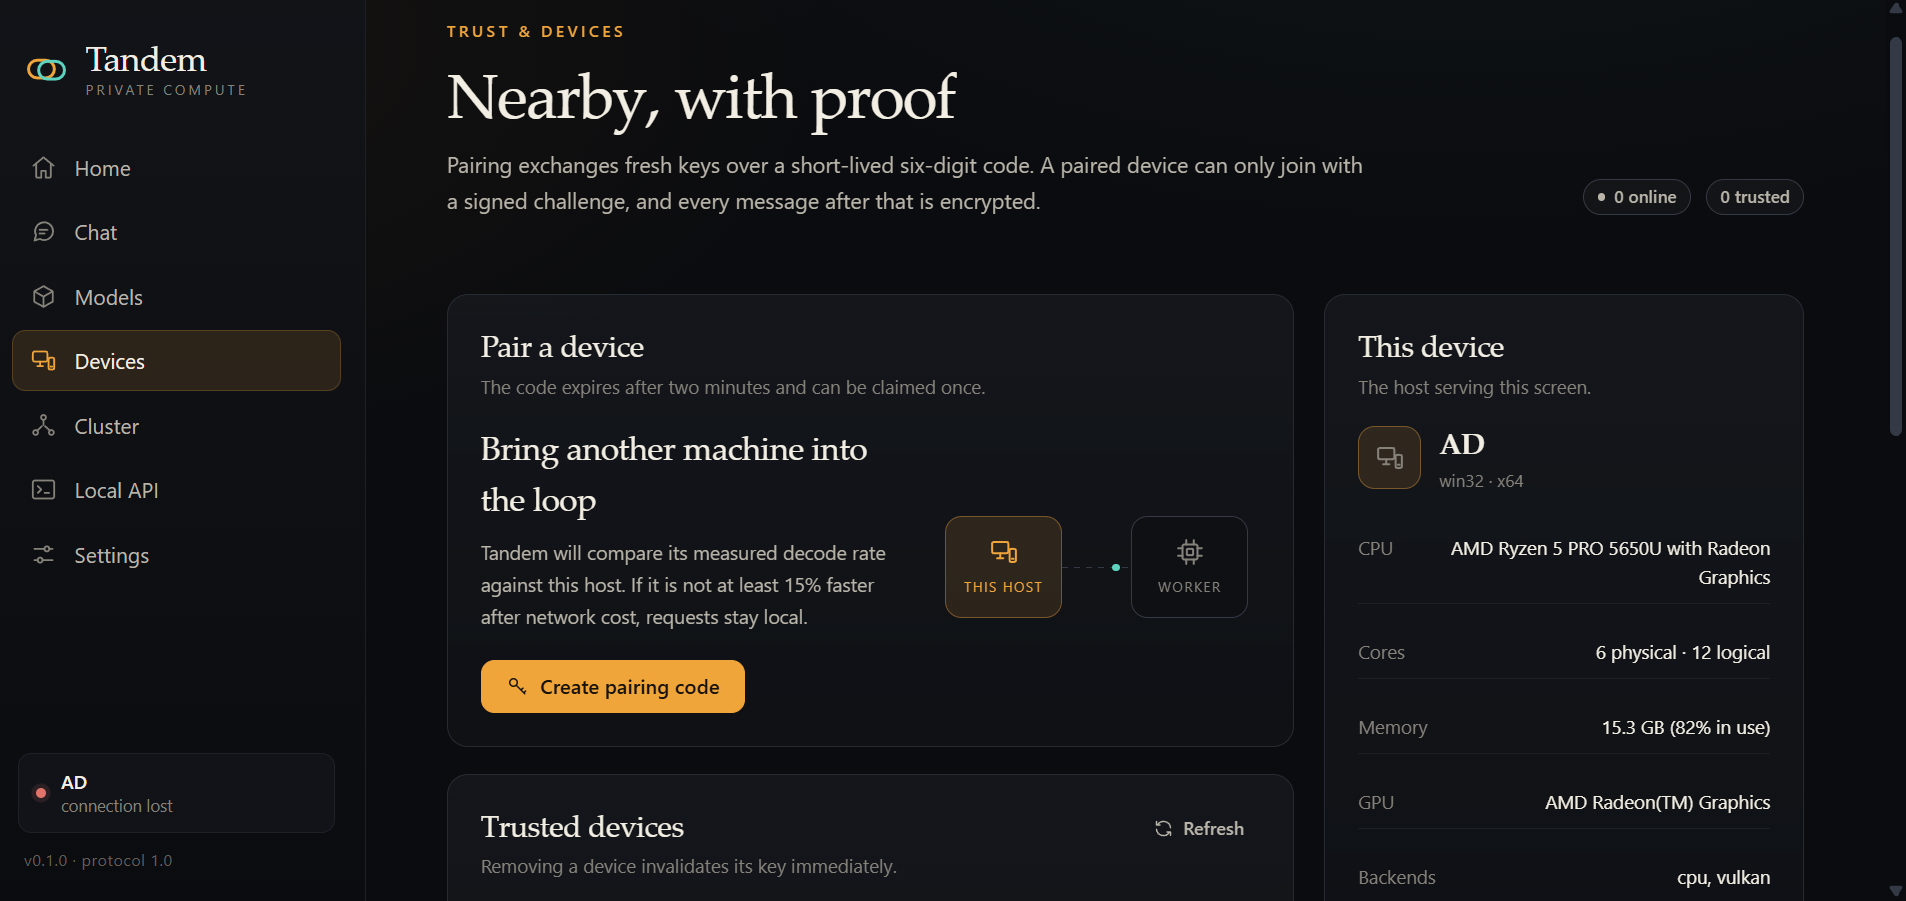
Tandem runs open models locally behind an OpenAI-compatible API. It can pool the memory of your laptop, phone and tablet to run a model too big for any one of them. Every connection is end-to-end encrypted, and each answer shows which device produced it.

Case study & proof
Tandem control room: local inference with the OpenAI-compatible API Tandem device pairing with encrypted, signed challenges
  • 18k+lines of code
  • 3platforms: Windows, Android, iOS
  • ~50tokens/s on a laptop GPU
  • 90+automated checks
  • AES-256encrypted device pairing

Also built

2026ECG denoisingButterworth filtering and spectral analysis in MATLABSignal processing–
2025CGM prediction modelsGlucose prediction from continuous-monitor dataData scienceGitHub ↗
2025AI in radiologyHow far clinical AI adoption has really goneReviewGitHub ↗

Credentials

Medicine is the hardest domain to fake. I'm trained in it.

Education

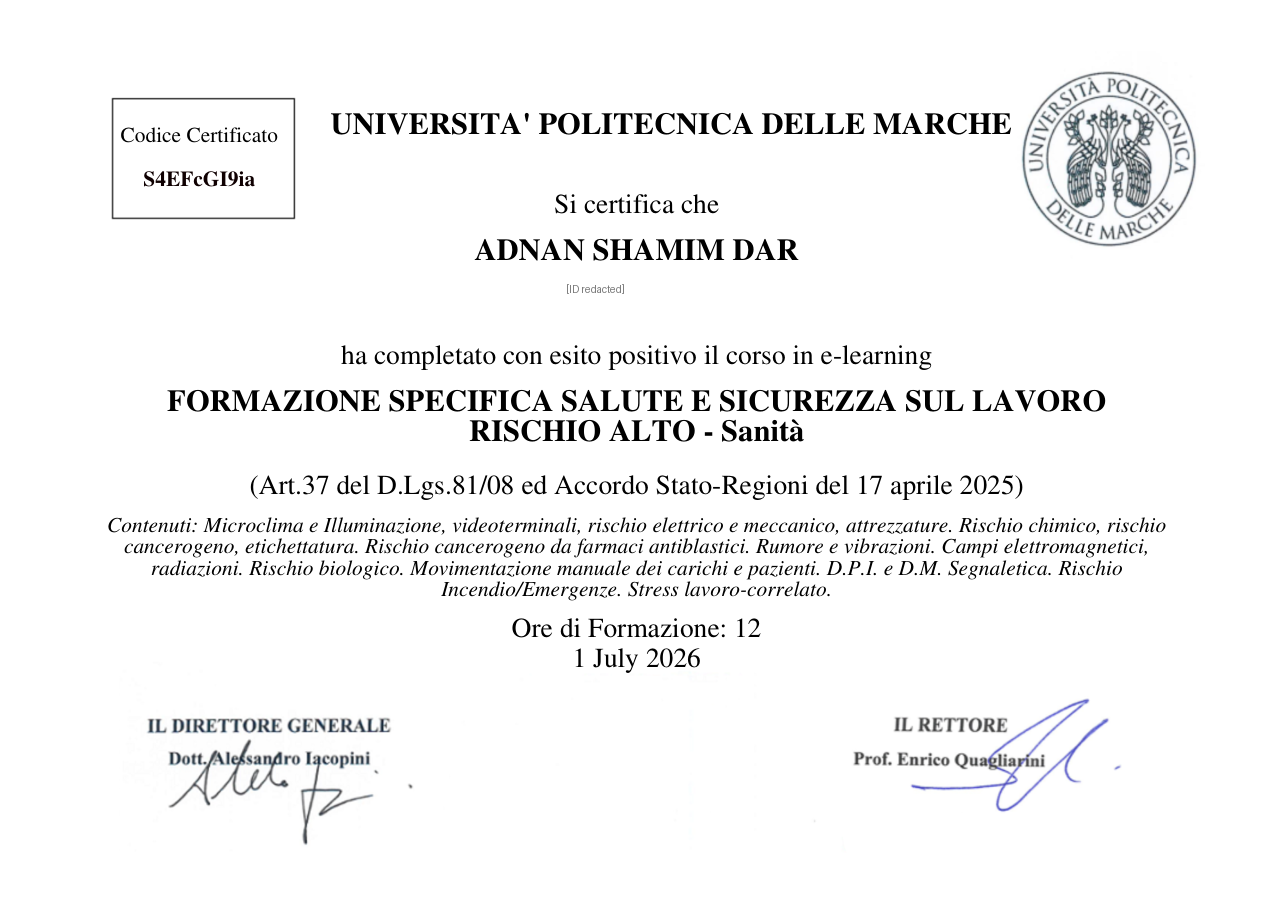
MD Candidate, Medicine & Surgery

Università Politecnica delle Marche · 2023–2029

  • Admitted 104th worldwide on the IMAT
  • ERDIS fully funded merit scholarship
  • Year 4 of 6
Case study & proof

Certifications

Evaluation

RLHF · rubric design · reviewer QA · hallucination checks · medical safety · red-teaming · function-calling · agent trajectories · video annotation

Research

Experimental design · ablations & null baselines · held-out validation · evidence provenance · LLM-as-judge

Engineering

Python · TypeScript · Kotlin · Swift · R · MATLAB · llama.cpp · OpenAI-compatible APIs

Languages

English (IELTS 8.5) · Italian · Arabic · Hindi · Urdu